Hi, I'm Twisha. I make AI models smaller and faster.
Mostly quantization, Mixture-of-Experts, and the systems that serve models. I like finding out what a "free" speedup really costs, and I build things at hackathons that sometimes don't stop at the hackathon.
Making models small
Quantization, and figuring out which weights actually deserve more bits.
Making them fast
Batching, queues, caches, backpressure: the plumbing between a model and its users.
Keeping it honest
Full-factorial benchmarks, bootstrap CIs, and agents that audit themselves.
Things I've built.
KAIROS
An autonomous ML research agent built around one uncomfortable finding: the validation set was lying.
CostPerThought
Three "free" speedups for reasoning models, stacked and priced in dollars per correct answer. One of them wasn't free at all.
Inference Gateway
A model server written from scratch. It batches, caches, and returns a clean 503 instead of falling over.
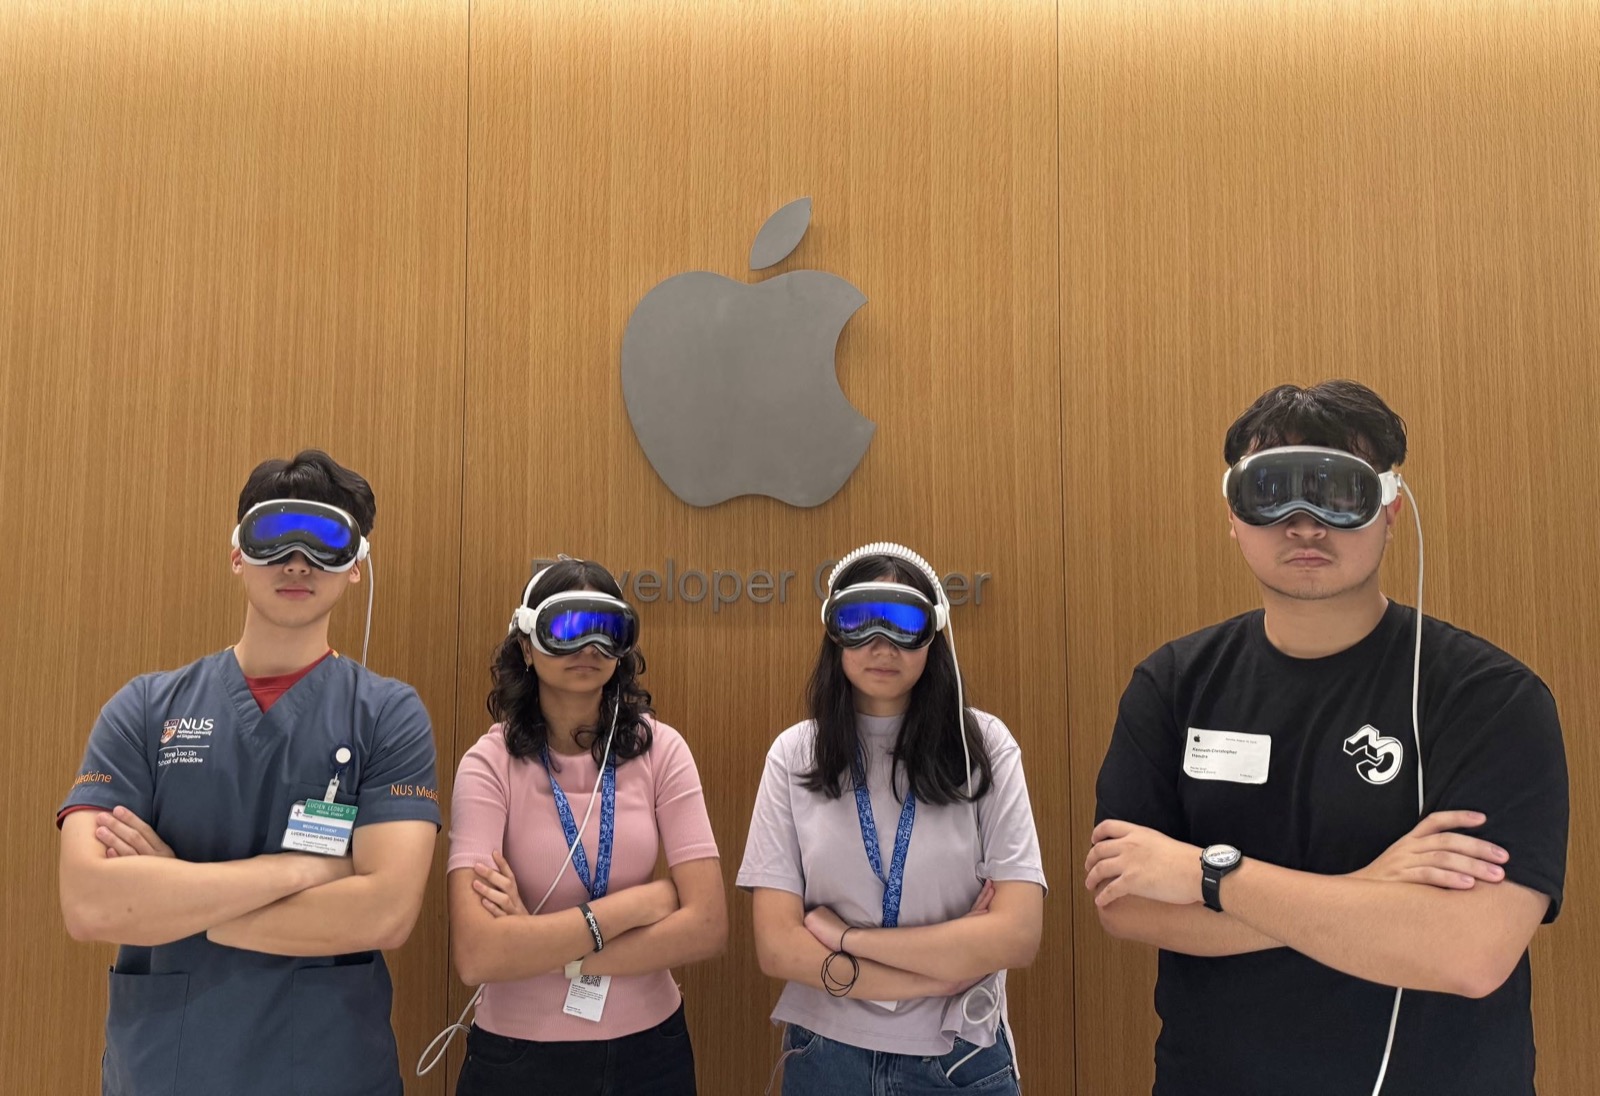
Spatial AI, for hospitals
2nd at Apple's Spatial AI Hacks. Now we're taking it to the people who'd actually use it.
Where I've been.
Model compression for Mixture-of-Experts serving: the DuoRate paper, 2-bit vision-language models, and a research agent that searched less.
Power BI dashboards for 8 SME clients, plus sales-forecasting and churn models.
A Laravel + MySQL CRM with auth, role-based access, and transactions.
Google Developer Group (Technology Associate) · NUS Women in Tech (Exco) · Top Student in AI Ethics
Lately, in photos.